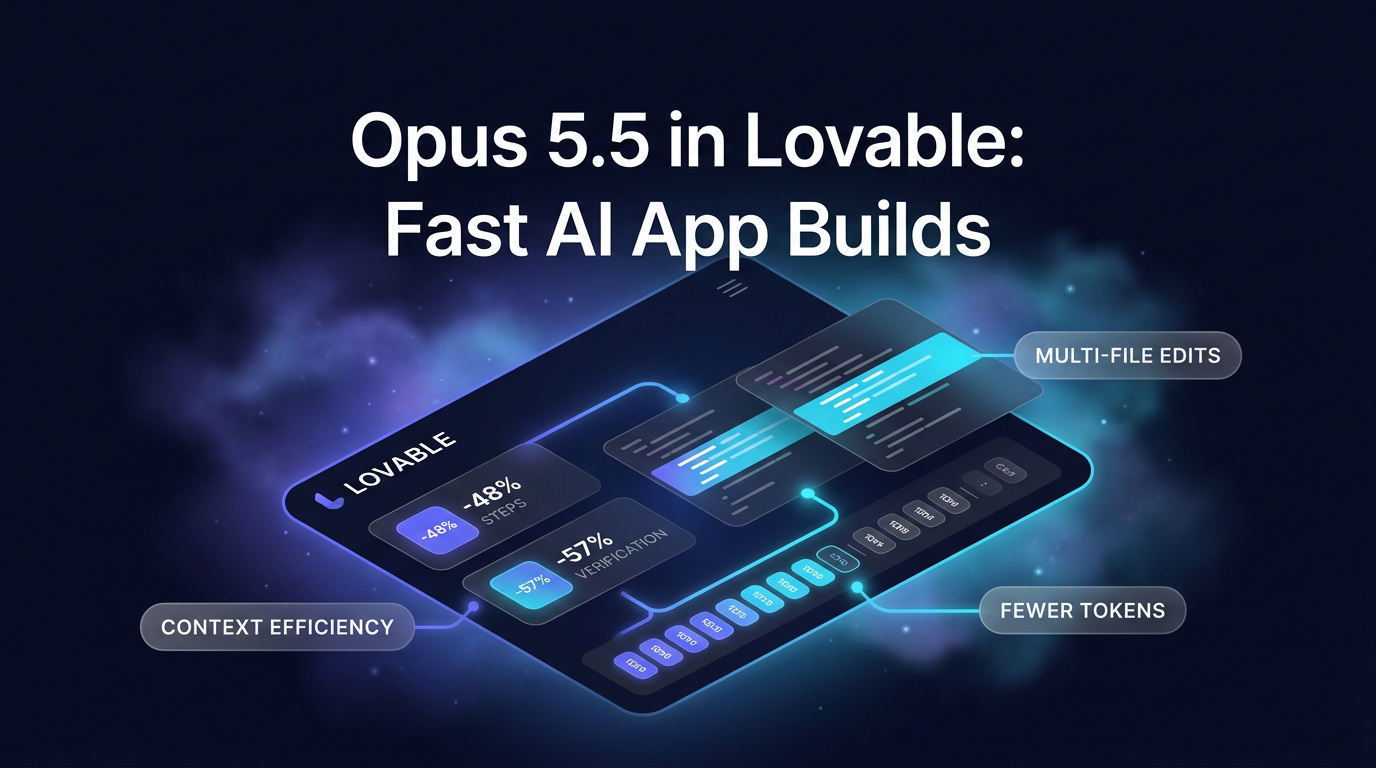
Opus 5.5 in Lovable is now available, bringing faster application builds and code modifications without reducing output quality. The platform announced that the updated model matches the output quality of Opus 5 while completing tasks in a third to half fewer steps. For builders creating software with generative tools, this update translates directly to reduced latency during complex edits and initial software generation.
As AI-assisted software generation matures, execution speed and token discipline have become major bottlenecks. The integration of Opus 5.5 in Lovable addresses these friction points directly by changing how the model gathers workspace context, writes patches, and inspects results. The official announcement was announced on the Lovable blog by CTO and co-founder Fabian Hedin, presenting verified internal benchmark numbers across varied task types.
Understanding the Architectural Changes in Opus 5.5 in Lovable
The speed improvements in the model stem from algorithmic refinements in how context, file discovery, and tool calling operate under the hood. Lovable identified three primary operational shifts that lower step counts across both fresh builds and established codebases without taking shortcuts or reducing code accuracy.
First, the model gathers context in a single pass. Rather than executing multiple exploratory turns to map out directory structures, read individual configurations, and check component hierarchies, the model chains file listings, search queries, and read commands into one command. It avoids circling back to re-inspect files between edits, which accounts for the majority of steps saved when modifying existing codebases.
Second, the model applies fewer and more complete edits. Instead of modifying a single file, checking the result, reading related files, and making secondary adjustments, it patches multiple files in one round. The resulting diffs are tighter and touch fewer files while achieving the exact functional requirements.
Third, verification discipline is significantly tighter. Previous models could spend a dozen turns re-running the same browser test or repeating validation checks on unchanged logic. The updated model inspects what a specific change requires, validates the outcome within budget, and stops instead of entering redundant evaluation loops.
How Lovable Evaluates Model Performance
Lovable evaluates candidate models against a standardized internal benchmark suite designed around real production app creation. The benchmark suite tests three primary operational workloads: 0-to-1 building from scratch, fixing and evolving existing codebases, and verification discipline.
The 0-to-1 building benchmark measures the model’s ability to construct a complete application from user prompts and achieve the desired functional outcome. Fixing and evolving existing codebases measures how effectively the model navigates live applications to add sub-features, resolve bugs, or rework user interfaces without breaking existing functionality. This category represents the largest volume of work builders carry out inside Lovable.
The verification discipline benchmark measures whether a model checks its work in proportion to the task requirements and then finishes within budget, rather than over-verifying, re-opening browser instances, or looping repeatedly on failed attempts. Lovable evaluated Opus 5.5 against Opus 5 across low, medium, and high reasoning effort levels on identical codebases, with each task run at least three times under consistent automated judges.
Step Reductions Across Task Categories with Opus 5.5 in Lovable
The benchmark data demonstrated substantial step reductions across all three tested categories. Every recorded delta achieved statistical significance at the 95 percent confidence level.
On 0-to-1 building tasks, the model reduced individual execution steps by 48 percent at low effort, 26 percent at medium effort, and 26 percent at high effort. On iterative code fixing tasks, steps decreased by 47 percent at low effort, 34 percent at medium effort, and 34 percent at high effort. On verification discipline tasks, steps fell by 57 percent at low effort, 46 percent at medium effort, and 42 percent at high effort.
In terms of benchmark success scores, Opus 5.5 scored level with Opus 5 on initial software creation and iterative code fixing tasks. On verification discipline benchmarks, Opus 5.5 scored 4 to 6 percent ahead of Opus 5 across every evaluated effort level.
Token Processing Reductions and Resource Footprint
The reduction in individual execution steps directly lowered the volume of tokens processed per task. Input tokens represent the contextual data that a model reads and re-reads across multi-turn tasks. Because the model gathers workspace context in a single pass, input token consumption fell significantly.
For 0-to-1 building tasks, input tokens processed per task dropped by 46 percent at low effort, 21 percent at medium effort, and 26 percent at high effort. On iterative code fixing, input tokens decreased by 36 percent at low effort, 27 percent at medium effort, and 29 percent at high effort. On verification discipline tasks, input tokens dropped by 59 percent at low effort, 46 percent at medium effort, and 41 percent at high effort.
Output token consumption also declined significantly during iterative tasks. Output tokens fell by 37 to 64 percent across iterative code fixing and verification discipline benchmarks. For 0-to-1 application builds, output token volumes remained close to Opus 5 levels, reflecting the reality that generating complete application codebases from scratch requires a consistent volume of syntax and structure.
Practical Implications for Software Builders
For founders and developers using AI to create web applications, Opus 5.5 in Lovable alters day-to-day productivity. Iterative code editing represents the largest category of work inside Lovable. When maintaining live applications, builders spend significant time prompting the model to add sub-features, correct visual bugs, or adjust data connections.
When an AI agent takes half as many steps to parse context and edit files, wait times drop sharply. Fewer intermediate tool calls also decrease the likelihood of hallucinated file paths or compounding syntax errors caused by fragmented multi-turn file edits. Clean, multi-file patches make it easier to audit code diffs and connect the generated output to modern web designing practices and custom backend workflows.
Furthermore, the reduction in unnecessary test cycles prevents the model from hitting execution timeouts or consuming credits on repetitive browser inspections. Builders get a tighter loop between prompt submission and runnable code, allowing faster feedback cycles during development sprints.
How This Fits Modern Automation Stacks
High-efficiency code generation models like Opus 5.5 in Lovable complement broader business automation ecosystems. When organizations build internal interfaces or customer portals, they frequently connect Lovable frontends with backend orchestration engines like Make.com, CRM databases in Go High Level, and autonomous AI automation pipelines.
A frontend that can be updated rapidly without breaking existing components makes agile software iterations feasible for small teams. When a database schema changes or a new API webhook is added, the model can update interface components in a single pass without unravelling surrounding logic.
By avoiding multiple fragmented file edits, the model helps maintain clean modular architectures. This structure makes it straightforward to pass structured JSON payloads between Lovable user interfaces and automated webhook endpoints without generating unexpected layout breakages or broken API bindings.
Frequently Asked Questions About Opus 5.5 in Lovable
Does Opus 5.5 sacrifice build quality to achieve faster speeds?
No. Benchmark testing demonstrated that the model matches the output quality of Opus 5 across 0-to-1 building and iterative code fixing benchmarks, while scoring 4 to 6 percent higher on verification discipline. The speed gains result from single-pass context collection and disciplined tool use rather than reduced evaluation rigor.
Why are input tokens reduced so significantly during codebase edits?
Input tokens represent the files, schemas, and workspace context the model reads during each turn. Because deploying Opus 5.5 in Lovable ensures that file discovery and read operations are chained into a single initial pass, the model avoids re-reading identical files between edit steps, cutting input token volume by up to 59 percent.
What is the verification discipline benchmark?
The verification discipline benchmark evaluates whether an AI model verifies a code change in proportion to the task requirements and stops within budget. It penalizes models that enter repetitive inspection loops, restart browser environments unnecessarily, or perform redundant validation checks on already functioning code.
Applying These Upgrades to Client Implementations
In client implementations, Wasif integrates generative frontend tools with robust backend automation architectures. When building client software and internal dashboards, the transition to faster, single-pass models like Opus 5.5 in Lovable reduces prototyping cycles while maintaining strict code standards. By pairing efficient web builders with structured CRM databases and automated webhook pipelines, systems remain easy to maintain and expand over time.
When deploying complex business tools, utilizing Opus 5.5 in Lovable alongside structured CRM databases and webhook handlers allows rapid iteration without technical debt. If you want to build automated software systems, modern web applications, or scalable CRM pipelines for your business, reach out to Wasif Ahmed to discuss your project.