Prices checked 18 November 2026
New AI models compared: between 12 November 2026 and 17 November 2026, 17 new model listings from HeyGen, OpenAI, Microsoft, ByteDance, Perplexity and Google appeared on OpenRouter. That is a lot to read. This guide puts them side by side in plain English: what each one does, what it costs, how big a job it can take and which one fits which kind of work.
Every price, limit and date comes from OpenRouter’s published data and was read on 18 November 2026. Prices change, so the date is part of the answer: if you read this later, open the linked page and compare.
New AI models compared: the quick answer
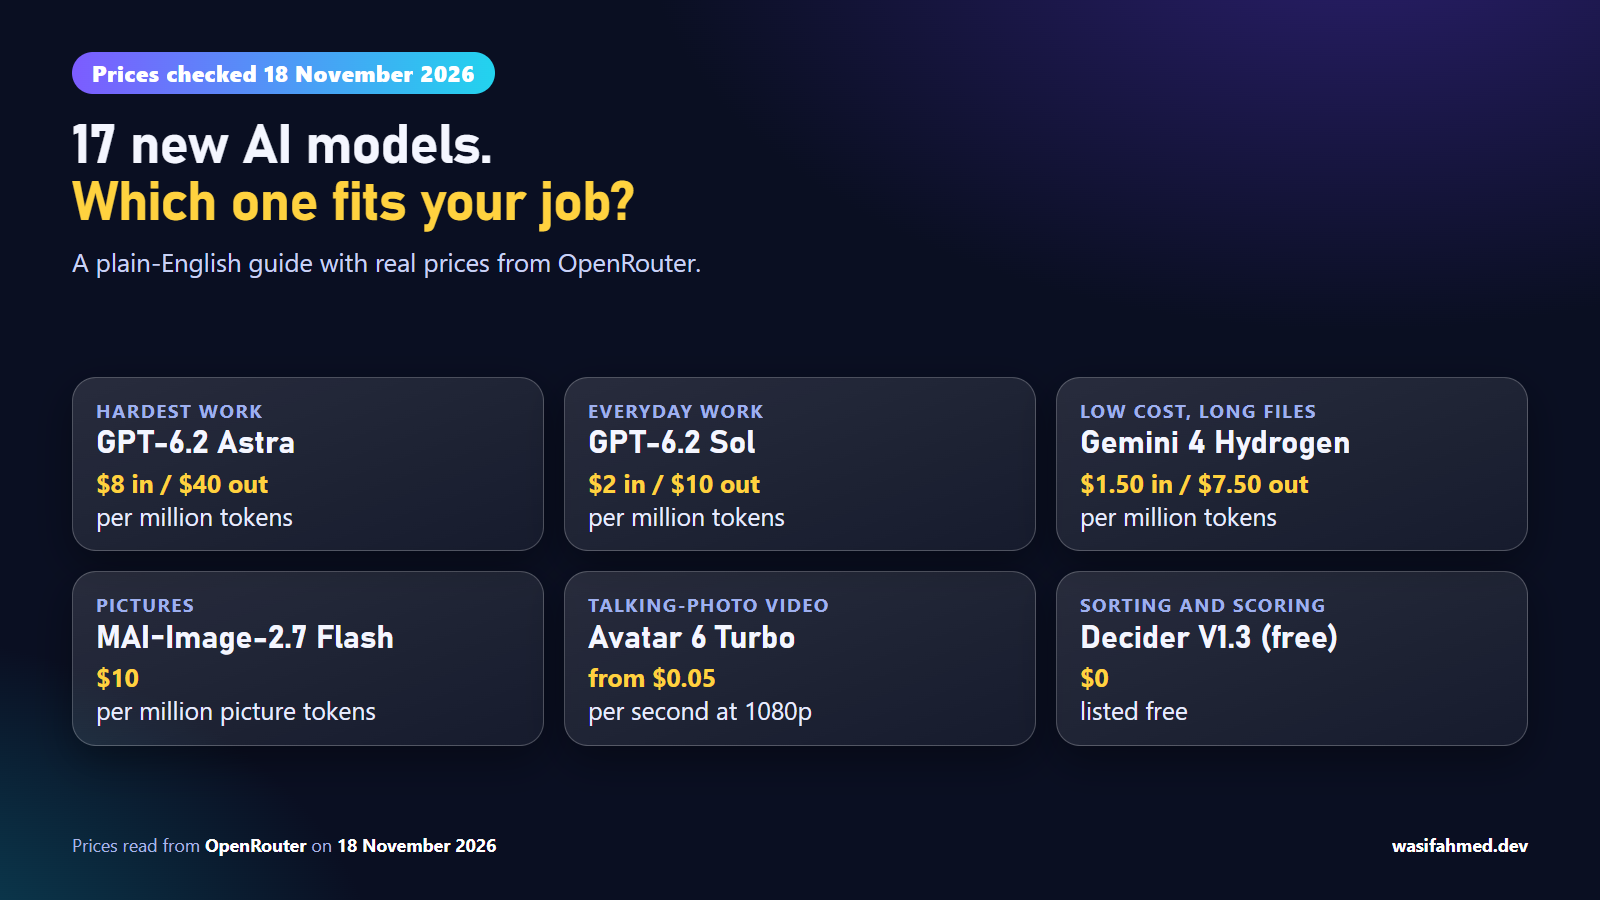
Short version, with prices read on 18 November 2026:
- The hardest work (engineering, research, big projects): GPT-6.2 Astra, $8 in / $40 out per million tokens.
- Everyday work (writing, multistep tasks, agents): GPT-6.2 Sol, $2 in / $10 out per million tokens.
- Cheap, huge or mixed jobs (long files, audio, video, big outputs): Gemini 4 Hydrogen, $1.50 in / $7.50 out per million tokens.
- Big jobs that can wait (overnight checks, bulk summaries): Gemini 4 Hydrogen (batch), $0.75 in / $3.75 out per million tokens.
- Pictures, fast and cheap: MAI-Image-2.7 Flash, $10 per million picture tokens.
- A talking-photo video from a voice recording: Avatar 6 Turbo, from $0.05 per second.
Not sure? Start with the cheaper option for your job and move up only when the answers are not good enough.
Three small words you need
- Token: a small piece of text, about three quarters of a word. Models charge by the million tokens.
- In and out: “in” is what you send, “out” is what the model writes back. Out is usually the pricier side.
- Reads at once: how much the model can hold in one request. One million tokens is roughly 750,000 words.
Words that change the price: Pro, Batch, Flash, Turbo, Lite and Free
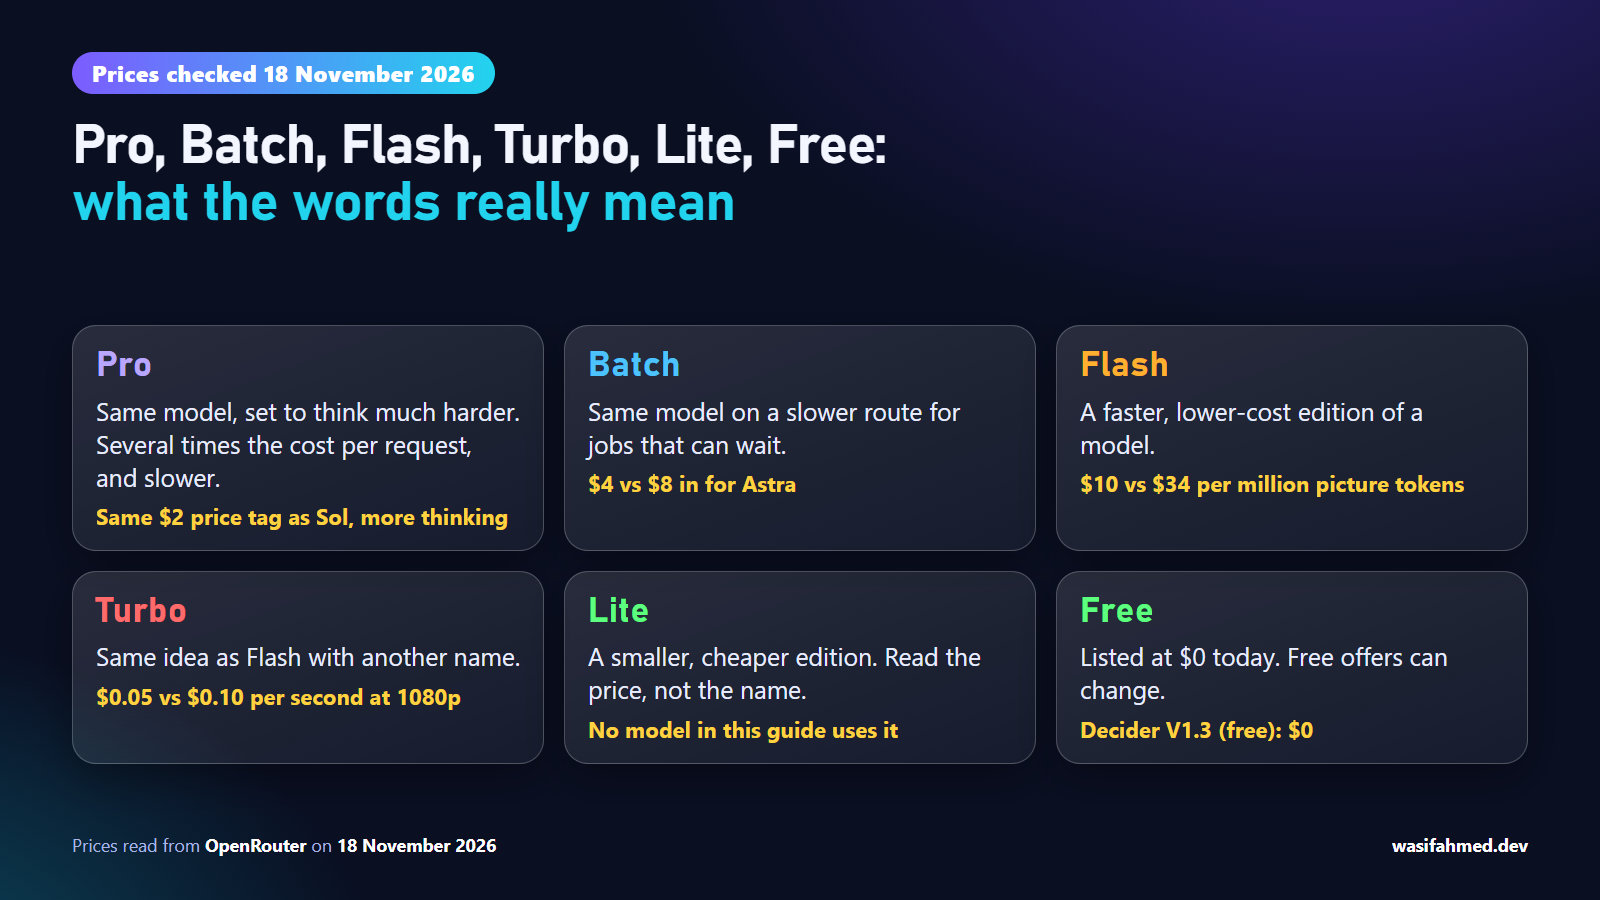
The names after the model name matter as much as the name itself. Here is what each word means, with the real numbers from this guide.
Batch
The same model, sent through OpenRouter’s batch route instead of the normal chat route. It is meant for jobs that can wait for the answer, such as checking hundreds of documents overnight.
In this guide: GPT-6.2 Astra Pro (batch), GPT-6.2 Astra (batch), GPT-6.2 Sol Pro (batch), Gemini 4 Hydrogen (batch).
GPT-6.2 Astra (batch) costs $4 per million input tokens, against $8 for the normal route: half the price.
Pro
The same underlying model, set to think much harder before it answers. OpenRouter notes that a typical request costs several times more than on the standard model and takes much longer, so Pro is for hard, high-stakes problems, not everyday chat.
In this guide: GPT-6.2 Astra Pro (batch), GPT-6.2 Astra Pro, GPT-6.2 Sol Pro (batch), GPT-6.2 Sol Pro.
GPT-6.2 Astra Pro has the same list price per token as GPT-6.2 Astra ($8 in, $40 out per million), but it uses far more thinking tokens per request, so the real bill is higher.
Flash
A faster, lower-cost edition of a model. Makers describe Flash editions as lower-latency and lower-cost, so check that the quality still fits your job.
In this guide: MAI-Image-2.7 Flash, Seedance 2.5 Flash, Decider Flash V1.3 (free).
MAI-Image-2.7 Flash lists $10 per million picture tokens, against $34 for MAI-Image-2.7.
Turbo
A faster, lower-cost variant of the main model, the same idea as Flash with a different name.
In this guide: Avatar 6 Turbo.
Avatar 6 Turbo starts at $0.05 per second of video, against $0.10 for Avatar 6.
Lite
Another word makers use for a smaller, cheaper edition. It is the same idea as Flash or Turbo, so always read the price and limits rather than trusting the name.
In this guide: no model carries this word.
None of the models in this edition is called Lite, so there is no Lite price to quote today.
Free
A model with a :free ending is listed at zero cost for the model itself. Free tiers can change, can be limited in how often you may call them, and a free price is not a promise for the future, which is why this page shows the date.
In this guide: Decider Flash V1.3 (free), Decider V1.3 (free).
Decider Flash V1.3 (free) is listed at $0 per million tokens on 18 November 2026.
Thinking and writing models
These are the models you chat with, or that write, analyse files and run agents. OpenAI added three GPT-6.2 models (Astra, Sol and their Pro forms) and Google added Gemini 4 Hydrogen.
| Model | Price | Reads at once | Longest answer | Can read | Score at High effort |
|---|---|---|---|---|---|
| GPT-6.2 Astra | $8 in $40 out | 1.05 million tokens | 128 thousand tokens | files, images, text | 60.1 (top 5 percent) |
| GPT-6.2 Astra (batch) Batch | $4 in $20 out | 1.05 million tokens | 128 thousand tokens | files, images, text | 60.1 (top 5 percent) |
| GPT-6.2 Sol | $2 in $10 out | 1.05 million tokens | 128 thousand tokens | files, images, text | 54.9 (top 13 percent) |
| Gemini 4 Hydrogen | $1.50 in $7.50 out | 1.05 million tokens | 944 thousand tokens | audio, files, images, text, video | 50.8 (top 22 percent) |
| Gemini 4 Hydrogen (batch) Batch | $0.75 in $3.75 out | 1.05 million tokens | 944 thousand tokens | audio, files, images, text, video | 50.8 (top 22 percent) |
| GPT-6.2 Astra Pro Pro | $8 in $40 out | 1.05 million tokens | 128 thousand tokens | files, images, text | not scored separately |
| GPT-6.2 Astra Pro (batch) Pro Batch | $4 in $20 out | 1.05 million tokens | 128 thousand tokens | files, images, text | not scored separately |
| GPT-6.2 Sol Pro Pro | $2 in $10 out | 1.05 million tokens | 128 thousand tokens | files, images, text | not scored separately |
| GPT-6.2 Sol Pro (batch) Pro Batch | $1 in $5 out | 1.05 million tokens | 128 thousand tokens | files, images, text | not scored separately |
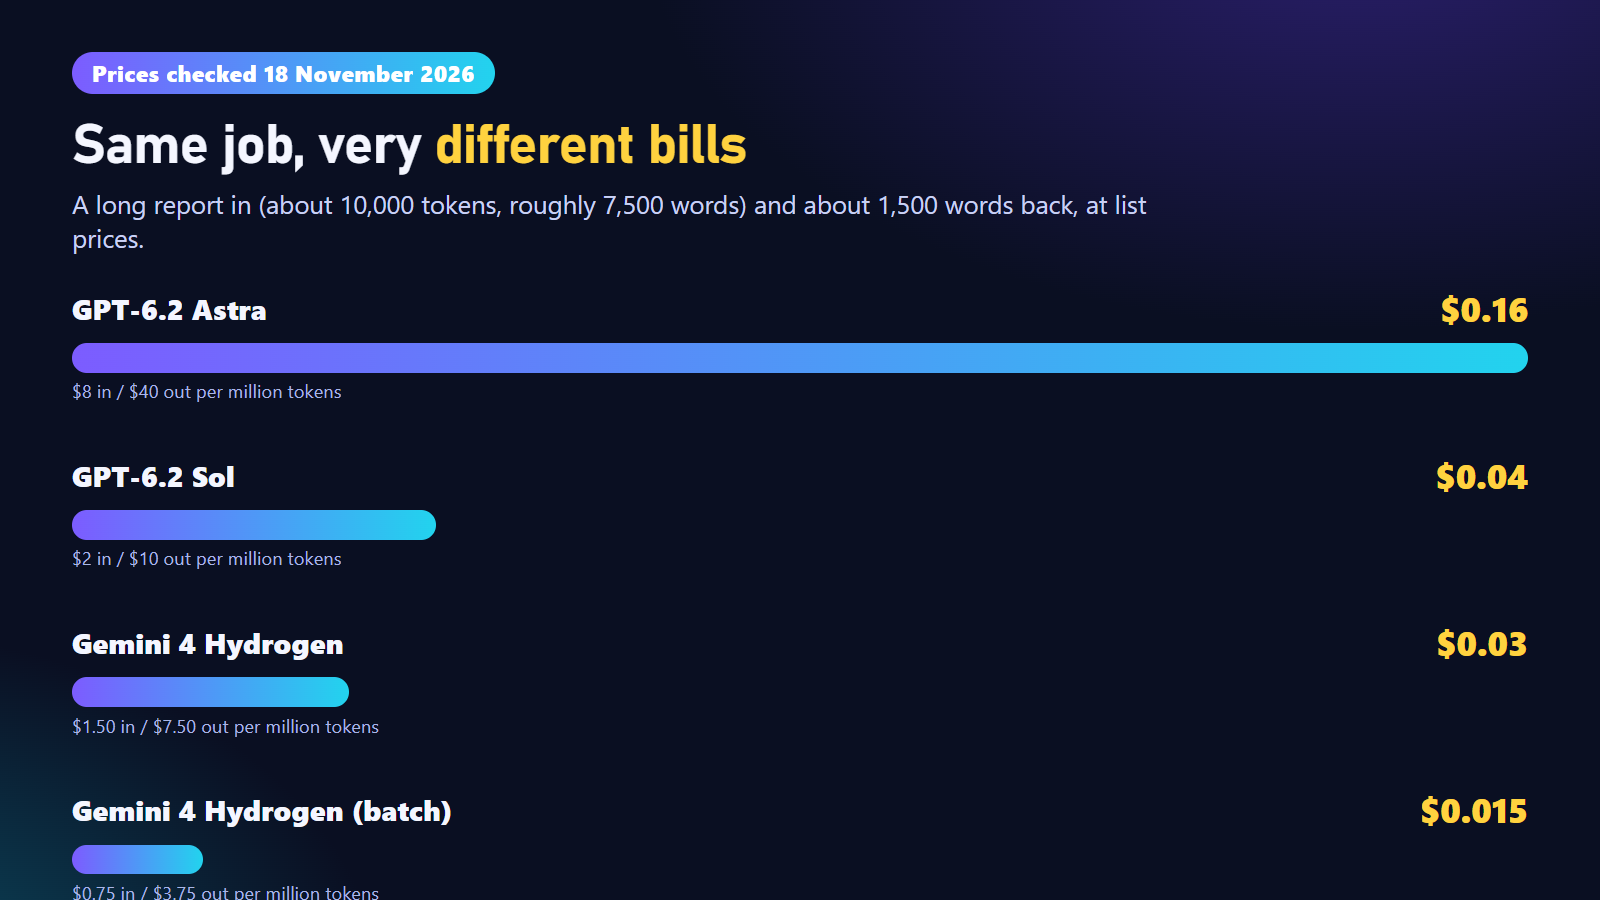
Here is a sum anyone can follow. A job that sends in about 10,000 tokens (roughly 7,500 words, like a long report) and gets back about 2,000 tokens (roughly 1,500 words) costs this much at the list prices of 18 November 2026:
| Model | Cost of the job |
|---|---|
| GPT-6.2 Astra | $0.16 |
| GPT-6.2 Astra (batch) Batch | $0.08 |
| GPT-6.2 Sol | $0.04 |
| Gemini 4 Hydrogen | $0.03 |
| Gemini 4 Hydrogen (batch) Batch | $0.015 |
This is arithmetic from the published prices, not a measured result. Models that think before they answer use extra thinking tokens, so a real bill can be higher.
Who each one is for
GPT-6.2 Astra
Pick it when: the work is hard and a wrong answer is costly: engineering, professional work or research. OpenAI calls it the flagship of the GPT-6.2 series.
Skip it when: you only need everyday writing or summaries. Sol does that at a quarter of the price.
GPT-6.2 Sol
Pick it when: you want a capable all-rounder for daily work. OpenAI places it below Astra as an efficient, versatile model for everyday work.
Skip it when: you need the highest score in the family, or you need to feed in audio or video (it reads text, images and files).
Gemini 4 Hydrogen
Pick it when: you need low cost and speed, or you have long, mixed material to read, since it takes audio, video, images, files and text. Google describes it as a high-efficiency workhorse for agents and coding.
Skip it when: you need the highest score in this group. It scored lower than both GPT-6.2 models at High effort.
GPT-6.2 Astra Pro
Pro
Pick it when: one single, high-stakes problem deserves the most thinking the model can do, and you can wait for the answer.
Skip it when: the job is routine. OpenRouter warns that Pro spends far more thinking tokens, so a typical request costs several times more.
GPT-6.2 Sol Pro
Pro
Pick it when: a hard question needs extra thinking but you want to stay on the cheaper Sol family.
Skip it when: you want quick, low-cost answers. Pro is slower and uses more thinking tokens.
More thinking means a higher score, a longer wait and a bigger bill
The Artificial Analysis Intelligence Index, shown on each OpenRouter model page and updated 18 November 2026, scores a model on a mix of hard tests. The same model scores differently depending on how long you let it think. Read it as one useful number, not the whole story.
GPT-6.2 Astra
GPT-6.2 Sol
Gemini 4 Hydrogen
For Gemini 4 Hydrogen, OpenRouter’s price list shows thinking tokens priced like answer tokens ($7.50 per million), so a higher thinking level can raise the cost as well as the score.
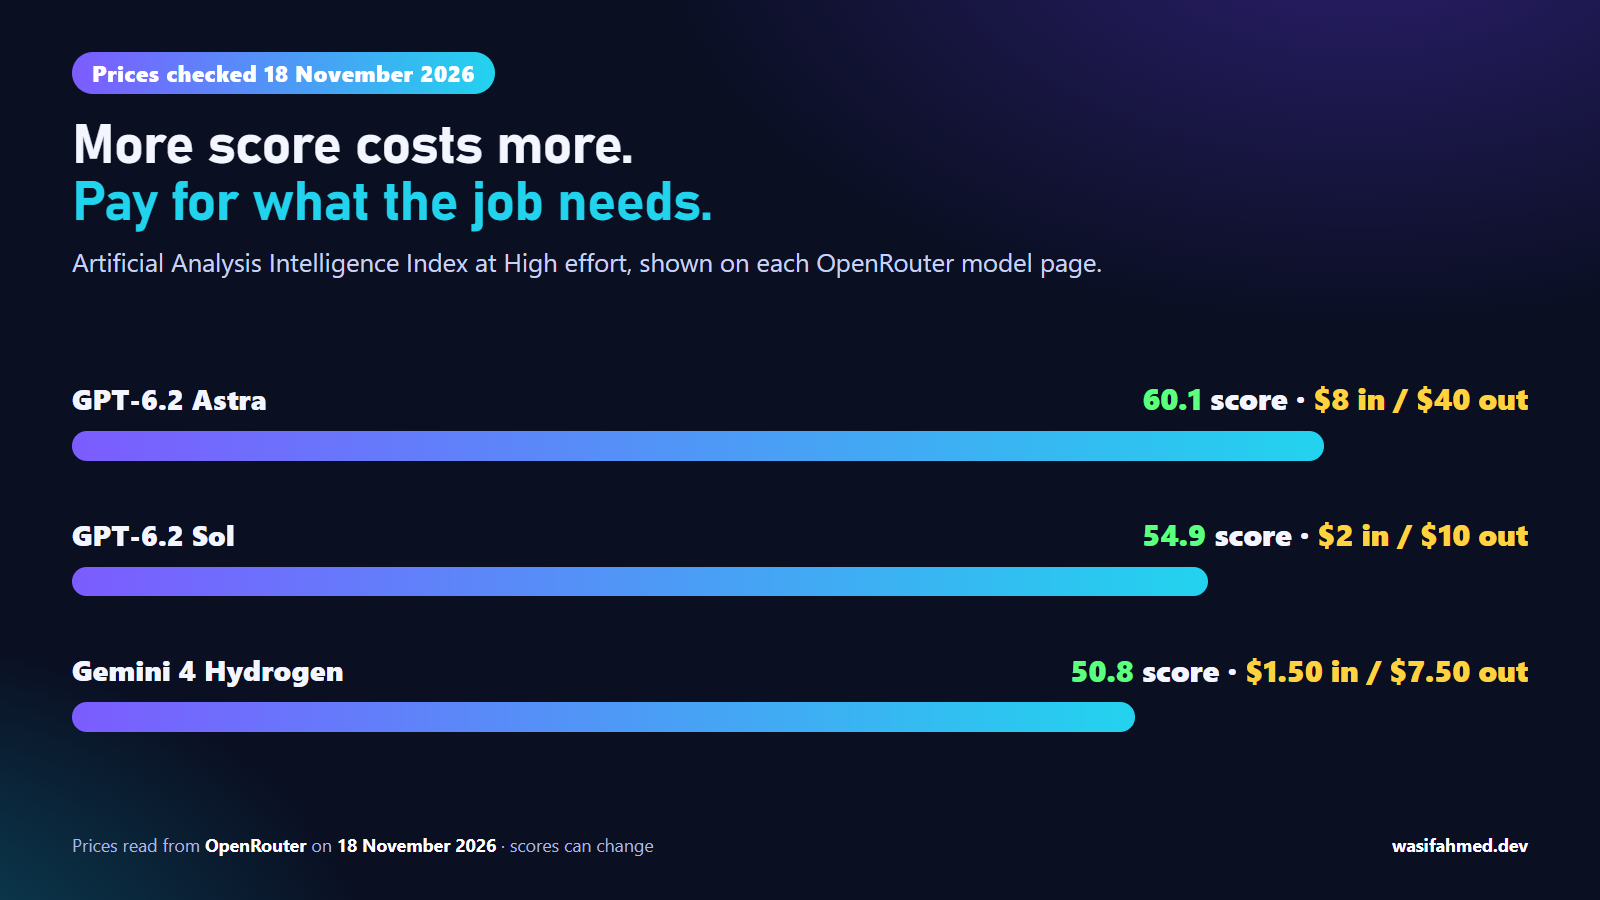
Notice the gap: GPT-6.2 Astra at Low effort (45.7) scores below GPT-6.2 Sol at High effort (54.9), and Sol costs a quarter of the price. For many jobs that makes Sol at a high setting the sensible start.
Picture models
Microsoft AI listed two models that generate and edit pictures: MAI-Image-2.7, which it calls the precision tier, and MAI-Image-2.7 Flash, the faster and lower-cost one.
| Model | Your words (text tokens) | Pictures made (picture tokens) | You can give it |
|---|---|---|---|
| MAI-Image-2.7 Flash Flash | $1.75 per million | $10 per million | text, images |
| MAI-Image-2.7 | $5 per million | $34 per million | text, images |
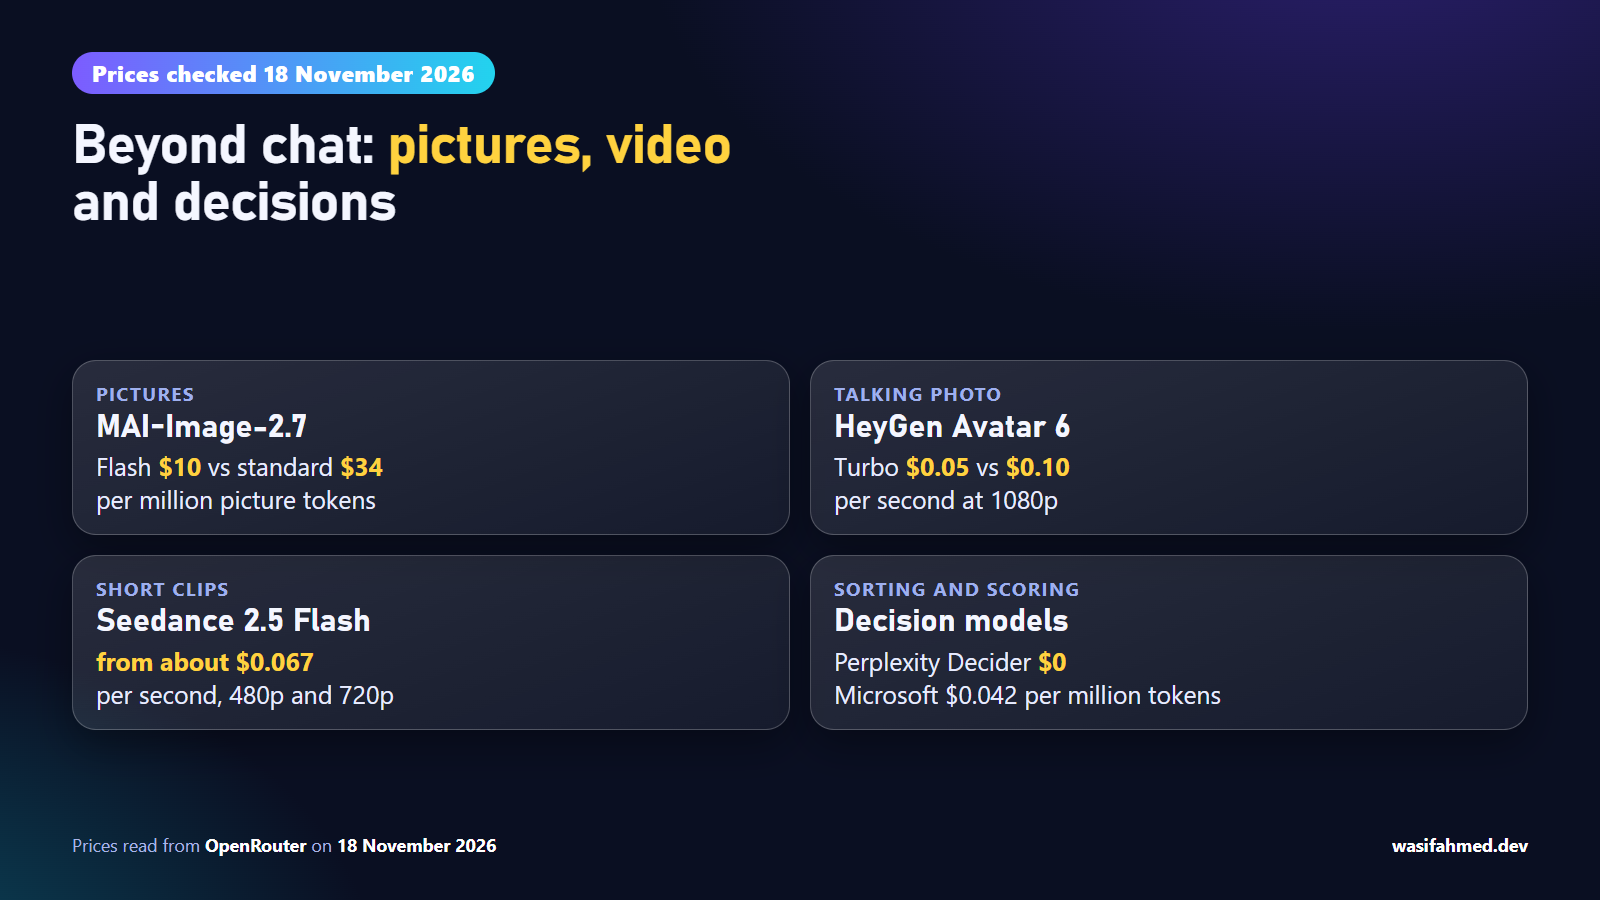
The Flash edition charges $10 per million picture tokens against $34 for the standard model. That is under a third. OpenRouter describes Flash as built for fast, high-volume work at comparable quality. Test both on your own sample pictures before you choose.
Video models
Two very different jobs sit here. HeyGen Avatar 6 turns one photo (or a short clip) plus an audio recording into a talking video: the audio sets the length. Seedance 2.5 Flash from ByteDance makes short clips from text, from an image or from reference footage, with optional generated sound.
| Model | Quality | Price | Length | You give it | Sound |
|---|---|---|---|---|---|
| Seedance 2.5 Flash Flash | 480p and 720p | from about $0.067 per second (as stated on OpenRouter’s model page) | 4 to 30 seconds | text, images, video, audio | can add sound |
| Avatar 6 | 1080p and 2K | $0.145 per second at 2K ($8.70 for a minute) $0.10 per second at 1080P ($6 for a minute) | set by your audio | text, images, video, audio | uses your audio |
| Avatar 6 Turbo Turbo | 1080p and 2K | $0.0875 per second at 2K ($5.25 for a minute) $0.05 per second at 1080P ($3 for a minute) | set by your audio | text, images, video, audio | uses your audio |
A real sum: a 60-second talking video costs $3 on Avatar 6 Turbo at 1080p, and $8.70 on Avatar 6 at 2K, at the list prices of 18 November 2026. Turbo is the cheaper, faster edition.
Decision models: a new kind of AI
A decision model does not chat. According to Microsoft’s description it reads the content you give it and returns a calibrated probability for each fixed answer option, so the answer carries its own confidence and your software can act, wait or ask for a human review. Perplexity’s Decider models work the same way and can answer yes or no questions, pick between up to 255 options or score against a rubric.
| Model | Price | Reads at once | Can read |
|---|---|---|---|
| Microsoft-Decision-1.1 | $0.042 per million tokens | 33 thousand tokens | text, images |
| Decider Flash V1.3 (free) Flash Free | $0 (free) | 262 thousand tokens | text, images |
| Decider V1.3 (free) Free | $0 (free) | 262 thousand tokens | text, images |
- Good for (from the makers’ descriptions): classification, routing, prioritising, verification, workflow control, agent guardrails, moderation and rubric grading.
- Not for: open-ended writing, conversation, translation or summaries. Use a chat model for those.
- Price: the two Perplexity Decider models are listed as free on 18 November 2026, and Microsoft-Decision-1.1 lists $0.042 per million tokens.
Which one should you choose?
Match the job, not the hype. Prices below were read on 18 November 2026.
| If you need | Choose | List price | Why |
|---|---|---|---|
| The hardest work (engineering, research, big projects) | GPT-6.2 Astra | $8 in / $40 out per million tokens | Highest published score in this group (60.1 on the Artificial Analysis Intelligence Index at High effort). Pay more only when the task is hard. |
| Everyday work (writing, multistep tasks, agents) | GPT-6.2 Sol | $2 in / $10 out per million tokens | A strong middle choice (54.9 at High effort) at a quarter of the top model’s price. |
| Cheap, huge or mixed jobs (long files, audio, video, big outputs) | Gemini 4 Hydrogen | $1.50 in / $7.50 out per million tokens | The lowest chat price in this group, 1.05 million tokens of memory and it also takes audio and video as input. |
| Big jobs that can wait (overnight checks, bulk summaries) | Gemini 4 Hydrogen (batch) | $0.75 in / $3.75 out per million tokens | The batch route lists half the price. You wait longer for the answers. |
| Pictures, fast and cheap | MAI-Image-2.7 Flash | $10 per million picture tokens | Built for quick, high-volume image making and editing at comparable quality, according to OpenRouter’s description. |
| A talking-photo video from a voice recording | Avatar 6 Turbo | from $0.05 per second | Turns one photo or short clip plus an audio track into a lip-synced talking video. |
| A short video clip from a text idea | Seedance 2.5 Flash | see the video table | Makes 480p and 720p clips of 4 to 30 seconds, with optional generated audio. |
| Free sorting, routing and rubric scoring | Decider Flash V1.3 (free) | $0 listed | Returns a probability for each answer instead of a chat reply, so your own code can sort or score content. |
Everyday tasks or specific ones?
- General everyday use (writing, summaries, questions): GPT-6.2 Sol at $2 / $10, or Gemini 4 Hydrogen at $1.50 / $7.50 if cost matters most.
- Specific hard work (engineering, research, complex projects): GPT-6.2 Astra at $8 / $40. Use a Pro edition only for a single, high-stakes problem.
- Specific media work: pictures with MAI-Image-2.7 (or Flash), talking videos with HeyGen Avatar 6 (or Turbo), short clips with Seedance 2.5 Flash.
- Sorting and judging content: a decision model, not a chat model.
Why one model can show several prices
The same model can cost different amounts depending on which company serves it and which route you use. This is why a quoted price always needs a date.
| Model | Prices across providers | Special routes | Very long requests |
|---|---|---|---|
| GPT-6.2 Astra | $8 / $40, $8.80 / $44, $9.60 / $48, $16 / $80, $24 / $120 | priority: $16 / $80; ultrafast: $24 / $120 | over 272,000 tokens in one request: $16 / $60 |
| GPT-6.2 Sol | $2 / $10, $2.20 / $11, $2.40 / $12, $4 / $20, $6 / $30 | priority: $4 / $20; ultrafast: $6 / $30 | over 272,000 tokens in one request: $4 / $15 |
| Gemini 4 Hydrogen | $0.75 / $3.75, $1.50 / $7.50, $1.65 / $8.25, $2.70 / $13.50 | flex: $0.75 / $3.75; priority: $2.70 / $13.50 | none listed |
Before you trust any score or price
- These models were listed on OpenRouter only days ago. Early scores can move as more tests are run.
- A score measures a mix of tests. Your own job may differ, so try a small real sample first.
- Prices, free tiers and limits can change at any time. Always check the date on this page.
Conclusion: the new AI models compared, in one simple rule
Here is the simple rule I would follow after reading any new AI models compared like this, as a view and not a test result: start with the cheapest model that fits the job, and move up only when the answers are not good enough.
- Hard, costly-if-wrong work: GPT-6.2 Astra ($8 in, $40 out). It had the highest published score in this group (60.1 at High effort).
- Daily work: GPT-6.2 Sol ($2 in, $10 out), a quarter of the top price.
- Big, mixed or budget jobs: Gemini 4 Hydrogen ($1.50 in, $7.50 out), which also reads audio and video.
- Jobs that can wait: the batch route lists half the price.
- Hardest single problem: a Pro edition, knowing it costs several times more and takes longer.
- Pictures, talking videos and clips: use the Flash and Turbo editions to keep costs down, and test quality on your own samples.
- Sorting and scoring content: a decision model, free from Perplexity on 18 November 2026.
Bookmark this page: the date at the top tells you exactly when the prices were read.
Questions people ask
What is the difference between GPT-6.2 Astra and GPT-6.2 Sol?
Astra is OpenAI’s flagship for the hardest projects and Sol is the efficient, everyday model below it. On 18 November 2026 Astra lists $8 in and $40 out per million tokens, Sol lists $2 in and $10 out, so Astra costs four times as much per token.
Is Gemini 4 Hydrogen cheaper than GPT-6.2 Sol?
Yes, at list prices on 18 November 2026: $1.50 in and $7.50 out per million tokens for Gemini 4 Hydrogen, against $2 and $10 for Sol. At the High thinking setting, Sol has the higher published score (54.9 against 50.8).
What does batch mean in a model name?
Batch means the same model sent through OpenRouter’s batch route, meant for jobs that can wait for the answer. On 18 November 2026 GPT-6.2 Astra on the batch route lists $4 in and $20 out, which is half the normal $8 and $40.
What does Pro mean for an AI model?
Pro means the same underlying model set to think much harder. OpenRouter warns that a typical Pro request costs several times more than the standard model and takes much longer, so it suits hard, high-stakes problems, not everyday chat.
What do Flash and Turbo mean?
Both words are used for a faster, lower-cost edition of a main model. In this edition MAI-Image-2.7 Flash, Seedance 2.5 Flash, Decider Flash V1.3 and HeyGen Avatar 6 Turbo are all described that way by OpenRouter.
What is the cheapest way to make a talking-photo video?
On 18 November 2026, HeyGen Avatar 6 Turbo lists $0.05 per second at 1080p, which is $3 for a minute. You supply one photo or short clip and an audio track.
What is a decision model?
A decision model does not chat. It reads text or images and returns a probability for each possible answer, so software can sort, route or score content. Perplexity Decider V1.3 is listed as free on 18 November 2026.
Are these prices final?
No. Every price in this guide was read from OpenRouter on 18 November 2026. Providers can change prices, so check the model page linked in the sources before you commit.
- Which AI Model Should You Use? 15 New Models Compared (Nov 2026): an earlier comparison on this site
- Gemini Decisions API: New Architecture for Fast Multimodal Choices: more on decision-style models
- ElevenLabs on OpenRouter: 11 New Voice Models Now Available: voice models on the same marketplace
Sources and method
I compiled this guide from published data. I have not run my own tests on these models, so nothing here is a personal benchmark.
- Prices, memory limits, inputs and release dates: OpenRouter’s public model list and each model’s page, read on 18 November 2026.
- Video prices: OpenRouter’s video model list and the model pages, read on 18 November 2026.
- Scores: the Artificial Analysis Intelligence Index as shown on each OpenRouter model page, last updated 18 November 2026.
- What each model does: the maker’s own description as printed on OpenRouter.
Model pages used:
- HeyGen: Avatar 6 Turbo (listed 17 November 2026)
- HeyGen: Avatar 6 (listed 17 November 2026)
- OpenAI: GPT-6.2 Astra Pro (batch) (listed 17 November 2026)
- OpenAI: GPT-6.2 Astra Pro (listed 17 November 2026)
- OpenAI: GPT-6.2 Astra (batch) (listed 17 November 2026)
- OpenAI: GPT-6.2 Astra (listed 17 November 2026)
- OpenAI: GPT-6.2 Sol Pro (batch) (listed 17 November 2026)
- OpenAI: GPT-6.2 Sol Pro (listed 17 November 2026)
- OpenAI: GPT-6.2 Sol (listed 17 November 2026)
- Microsoft: MAI-Image-2.7 Flash (listed 17 November 2026)
- Microsoft: MAI-Image-2.7 (listed 17 November 2026)
- Microsoft: Microsoft-Decision-1.1 (listed 17 November 2026)
- ByteDance: Seedance 2.5 Flash (listed 17 November 2026)
- Perplexity: Decider Flash V1.3 (free) (listed 12 November 2026)
- Perplexity: Decider V1.3 (free) (listed 12 November 2026)
- Google: Gemini 4 Hydrogen (batch) (listed 12 November 2026)
- Google: Gemini 4 Hydrogen (listed 12 November 2026)
Last updated 18 November 2026. Prices and scores will change; the date above is your reference.